biosppy.clustering
biosppy.clustering
This module provides various unsupervised machine learning (clustering) algorithms.
- copyright:
2015-2026 by Instituto de Telecomunicacoes
- license:
BSD 3-clause, see LICENSE for more details.
Functions
|
Template selection based on cluster centroids. |
|
Extract the consensus partition from a co-association matrix using hierarchical agglomerative methods. |
|
Perform clustering based in an ensemble of partitions. |
|
Perform clustering based on an ensemble of k-means partitions. |
|
Create the co-association matrix from a clustering ensemble. |
|
Create an ensemble of partitions of the data using the given clustering method. |
|
Perform clustering using the DBSCAN algorithm [EKSX96]. |
|
Perform clustering using hierarchical agglomerative algorithms. |
|
Perform clustering using the k-means algorithm. |
|
Template selection based on the MDIST method [UlRJ04]. |
|
Perform outlier removal using the DBSCAN algorithm. |
|
Perform outlier removal using the DMEAN algorithm [LCSF13]. |
- biosppy.clustering.centroid_templates(data=None, clusters=None, ntemplates=1)[source]
Template selection based on cluster centroids.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each cluster.
ntemplates (int, optional) – Number of templates to extract; if more than 1, k-means is used to obtain more templates.
- Returns:
templates (array) – Selected templates from the input data.
- biosppy.clustering.coassoc_partition(coassoc=None, k=0, linkage='average')[source]
Extract the consensus partition from a co-association matrix using hierarchical agglomerative methods.
- Parameters:
coassoc (array) – Co-association matrix.
k (int, optional) – Number of clusters to extract; if 0 uses the life-time criterion.
linkage (str, optional) – Linkage criterion for final partition extraction; one of ‘average’, ‘complete’, ‘single’, or ‘weighted’.
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each found cluster; outliers have key -1; clusters are assigned integer keys starting at 0.
- biosppy.clustering.consensus(data=None, k=0, linkage='average', fcn=None, grid=None)[source]
Perform clustering based in an ensemble of partitions.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
k (int, optional) – Number of clusters to extract; if 0 uses the life-time criterion.
linkage (str, optional) – Linkage criterion for final partition extraction; one of ‘average’, ‘centroid’, ‘complete’, ‘median’, ‘single’, ‘ward’, or ‘weighted’.
fcn (function) – A clustering function.
grid (dict, list, optional) – A (list of) dictionary with parameters for each run of the clustering method (see sklearn.model_selection.ParameterGrid).
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each found cluster; outliers have key -1; clusters are assigned integer keys starting at 0.
- biosppy.clustering.consensus_kmeans(data=None, k=0, linkage='average', nensemble=100, kmin=None, kmax=None)[source]
Perform clustering based on an ensemble of k-means partitions.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
k (int, optional) – Number of clusters to extract; if 0 uses the life-time criterion.
linkage (str, optional) – Linkage criterion for final partition extraction; one of ‘average’, ‘centroid’, ‘complete’, ‘median’, ‘single’, ‘ward’, or ‘weighted’.
nensemble (int, optional) – Number of partitions in the ensemble.
kmin (int, optional) – Minimum k for the k-means partitions; defaults to
 .
kmax (int, optional) – Maximum k for the k-means partitions; defaults to
 .
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each found cluster; outliers have key -1; clusters are assigned integer keys starting at 0.
- biosppy.clustering.create_coassoc(ensemble=None, N=None)[source]
Create the co-association matrix from a clustering ensemble.
- Parameters:
ensemble (list) – Clustering ensemble partitions.
N (int) – Number of data samples.
- Returns:
coassoc (array) – Co-association matrix.
- biosppy.clustering.create_ensemble(data=None, fcn=None, grid=None)[source]
Create an ensemble of partitions of the data using the given clustering method.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
fcn (function) – A clustering function.
grid (dict, list, optional) – A (list of) dictionary with parameters for each run of the clustering method (see sklearn.model_selection.ParameterGrid).
- Returns:
ensemble (list) – Obtained ensemble partitions.
- biosppy.clustering.dbscan(data=None, min_samples=5, eps=0.5, metric='euclidean', metric_args=None)[source]
Perform clustering using the DBSCAN algorithm [EKSX96].
The algorithm works by grouping data points that are closely packed together (with many nearby neighbors), marking as outliers points that lie in low-density regions.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
min_samples (int, optional) – Minimum number of samples in a cluster.
eps (float, optional) – Maximum distance between two samples in the same cluster.
metric (str, optional) – Distance metric (see scipy.spatial.distance).
metric_args (dict, optional) – Additional keyword arguments to pass to the distance function.
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each found cluster; outliers have key -1; clusters are assigned integer keys starting at 0.
References
- biosppy.clustering.hierarchical(data=None, k=0, linkage='average', metric='euclidean', metric_args=None)[source]
Perform clustering using hierarchical agglomerative algorithms.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
k (int, optional) – Number of clusters to extract; if 0 uses the life-time criterion.
linkage (str, optional) – Linkage criterion; one of ‘average’, ‘centroid’, ‘complete’, ‘median’, ‘single’, ‘ward’, or ‘weighted’.
metric (str, optional) – Distance metric (see ‘biosppy.metrics’).
metric_args (dict, optional) – Additional keyword arguments to pass to the distance function.
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each found cluster; outliers have key -1; clusters are assigned integer keys starting at 0.
- Raises:
TypeError – If ‘metric’ is not a string.
ValueError – When the ‘linkage’ is unknown.
ValueError – When ‘metric’ is not ‘euclidean’ when using ‘centroid’, ‘median’, or ‘ward’ linkage.
ValueError – When ‘k’ is larger than the number of data samples.
- biosppy.clustering.kmeans(data=None, k=None, init='random', max_iter=300, n_init=10, tol=0.0001)[source]
Perform clustering using the k-means algorithm.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
k (int) – Number of clusters to extract.
init (str, array, optional) – If string, one of ‘random’ or ‘k-means++’; if array, it should be of shape (n_clusters, n_features), specifying the initial centers.
max_iter (int, optional) – Maximum number of iterations.
n_init (int, optional) – Number of initializations.
tol (float, optional) – Relative tolerance to declare convergence.
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for each found cluster; outliers have key -1; clusters are assigned integer keys starting at 0.
- biosppy.clustering.mdist_templates(data=None, clusters=None, ntemplates=1, metric='euclidean', metric_args=None)[source]
Template selection based on the MDIST method [UlRJ04].
Extends the original method with the option of also providing a data clustering, in which case the MDIST criterion is applied for each cluster [LCSF14].
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
clusters (dict, optional) – Dictionary with the sample indices (rows from data) for each cluster.
ntemplates (int, optional) – Number of templates to extract.
metric (str, optional) – Distance metric (see scipy.spatial.distance).
metric_args (dict, optional) – Additional keyword arguments to pass to the distance function.
- Returns:
templates (array) – Selected templates from the input data.
References
[UlRJ04] (1,2)U. Uludag, A. Ross, A. Jain, “Biometric template selection and update: a case study in fingerprints”, Pattern Recognition 37, 2004
[LCSF14]A. Lourenco, C. Carreiras, H. Silva, A. Fred, “ECG biometrics: A template selection approach”, 2014 IEEE International Symposium on Medical Measurements and Applications (MeMeA), 2014
- biosppy.clustering.outliers_dbscan(data=None, min_samples=5, eps=0.5, metric='euclidean', metric_args=None)[source]
Perform outlier removal using the DBSCAN algorithm.
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
min_samples (int, optional) – Minimum number of samples in a cluster.
eps (float, optional) – Maximum distance between two samples in the same cluster.
metric (str, optional) – Distance metric (see scipy.spatial.distance).
metric_args (dict, optional) – Additional keyword arguments to pass to the distance function.
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for the outliers (key -1) and the normal (key 0) groups.
templates (dict) – Elements from ‘data’ for the outliers (key -1) and the normal (key 0) groups.
- biosppy.clustering.outliers_dmean(data=None, alpha=0.5, beta=1.5, metric='euclidean', metric_args=None, max_idx=None)[source]
Perform outlier removal using the DMEAN algorithm [LCSF13].
- A sample is considered valid if it cumulatively verifies:
distance to average template smaller than a (data derived) threshold ‘T’;
sample minimum greater than a (data derived) threshold ‘M’;
sample maximum smaller than a (data derived) threshold ‘N’;
position of the sample maximum is the same as the given index [optional].
For a set of

 samples:
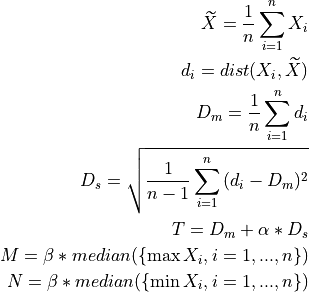
- Parameters:
data (array) – An m by n array of m data samples in an n-dimensional space.
alpha (float, optional) – Parameter for the distance threshold.
beta (float, optional) – Parameter for the maximum and minimum thresholds.
metric (str, optional) – Distance metric (see scipy.spatial.distance).
metric_args (dict, optional) – Additional keyword arguments to pass to the distance function.
max_idx (int, optional) – Index of the expected maximum.
- Returns:
clusters (dict) – Dictionary with the sample indices (rows from ‘data’) for the outliers (key -1) and the normal (key 0) groups.
templates (dict) – Elements from ‘data’ for the outliers (key -1) and the normal (key 0) groups.
References